Fonts and Unicode
Besides the limited set of latin fonts built into the PDF format, fpdf2 offers full support for using and embedding Unicode (TrueType "ttf" and OpenType "otf") fonts. To keep the output file size small, it only embeds the subset of each font that is actually used in the document. This part of the code has been completely rewritten since the fork from PyFPDF. It uses the fonttools library for parsing the font data, and harfbuzz (via uharfbuzz) for text shaping.
To make use of that functionality, you have to install at least one Unicode font, either in the system font folder or in some other location accessible to your program. For professional work, many designers prefer commercial fonts, suitable to their specific needs. There are also many sources of free TTF fonts that can be downloaded online and used free of cost (some of them may have restrictions on commercial redistribution, such as server installations or including them in a software project).
-
Font Library - A collection of fonts for many languages with an open source type license.
-
Google Fonts - A collection of free to use fonts for many languages.
-
Microsoft Font Library - A large collection of fonts that are free to use.
-
GitHub: Fonts - Links to public repositories of open source font projects as well as font related software projects.
-
GNU FreeFont family: FreeSans, FreeSerif, FreeMono
To use a Unicode font in your program, use the add_font(), and then the set_font() method calls.
Web fonts (WOFF and WOFF2)
WOFF and WOFF2 are web-optimized, compressed containers for TrueType and OpenType fonts, designed to reduce download size for browsers. fpdf2 supports these formats by decompressing them before embedding the resulting font data into the generated PDF.
Font collections (TTC/OTC)
TrueType and OpenType collections bundle multiple font faces into a single file. When adding a collection with add_font(), you can choose which face to load using the collection_font_number argument. If not specified, it defaults to 0 (the first face in the collection).
Built-in Fonts vs. Unicode Fonts
The PDF file format knows a small number of "standard" fonts, namely Courier, Helvetica, Times, Symbol, and ZapfDingbats. The first three are available in regular, bold, italic, and bold-italic versions. This gives us a set of fonts known as "14 Standard PDF fonts". Any PDF processor (eg. a viewer) must provide those fonts for display. To use them, you don't need to call .add_font(), but only .set_font().
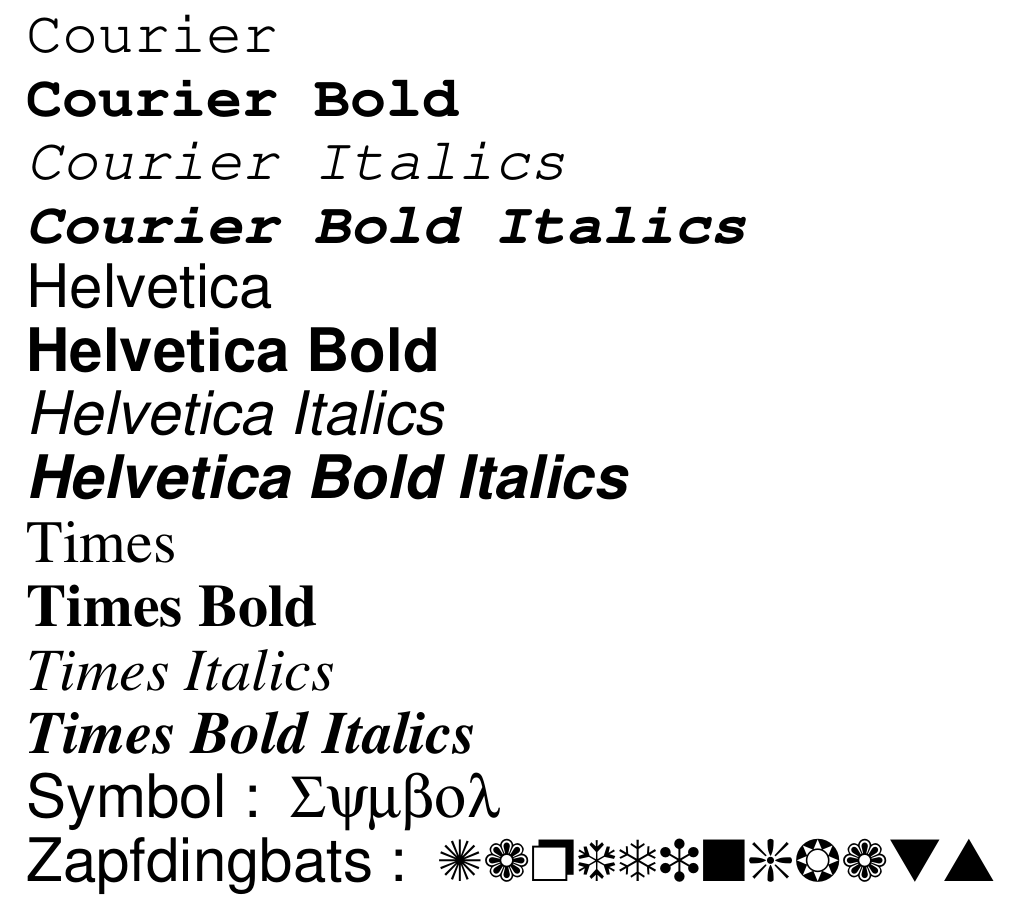
( script used to generate this: tutorial/core_fonts.py )
While that may seem convenient, there's a big drawback. Those fonts only support latin characters, or a set of special characters for the last two. If you try to render any Unicode character outside of those ranges, then you'll get an error like: "Character "θ" at index 13 in text is outside the range of characters supported by the font used: "courier". Please consider using a Unicode font.". So if you want to create documents with any characters other than those common in English and a small number of european languages, then you need to add a Unicode font containing the respective glyph as described in this document.
Note that even if you have a font eg. named "Courier" installed as a system font on your computer, by default this will not be used. You'll have to explicitly call eg. .add_font("Courier2", fname=r"C:\Windows\Fonts\cour.ttf") to make it available. If the name is really the same (ignoring case), then you'll have to use a suitable variation, since trying to overwrite one of the "standard" names with .add_font() will result in an error.
Automatic font detection and helpful error messages
When text cannot be encoded with the current font, the FPDFUnicodeEncodingException raised by fpdf2 does more than report the offending character: it identifies the Unicode script of the text (Cyrillic, Arabic, Chinese, Devanagari, etc.) and, when a suitable font is found already installed on the machine running the code, suggests one together with the exact add_font() call to use. For example, rather than only "Character "θ" ... Please consider using a Unicode font", you may get a message pointing you to a specific font file and the line of code that enables it.
The suggestions prefer freely-licensed, broad-coverage font families such as DejaVu, Noto and Liberation. fpdf2 never bundles or distributes these fonts — it only points to fonts that are already present on your system, so no additional font licensing obligations are introduced by this feature. You remain responsible for the licensing of whichever font you ultimately embed in your document.
This behaviour is powered by the internal UnicodeFontManager helper. It is not part of the public API and may change without notice, but the same detection logic is available through the convenience functions get_unicode_font_recommendation(text) and suggest_unicode_font_for_error(text, font_name) in fpdf.unicode_font_utils. A runnable walk-through is provided in the tutorial below:
#!/usr/bin/env python
"""
Unicode Font Detection and Management Tutorial

This tutorial demonstrates how to use fpdf2's new Unicode font detection
and management features to automatically handle different scripts like
Cyrillic, Arabic, Chinese, etc.
"""

from fpdf import FPDF
from fpdf.unicode_font_utils import (
    UnicodeFontManager,
    get_unicode_font_recommendation,
    suggest_unicode_font_for_error,
)
from fpdf.unicode_script import UnicodeScript


def demonstrate_unicode_font_detection():
    """Demonstrate automatic Unicode font detection and recommendations."""

    print("=== Unicode Font Detection Demo ===\n")

    # Initialize the font manager
    manager = UnicodeFontManager()

    # List available fonts
    print("Available Unicode fonts on this system:")
    available_fonts = manager.list_available_unicode_fonts()
    for font_name, font_path in list(available_fonts.items())[:5]:  # Show first 5
        print(f"  - {font_name}: {font_path}")
    if len(available_fonts) > 5:
        print(f"  ... and {len(available_fonts) - 5} more fonts")
    print()

    # Test different scripts
    test_texts = [
        ("English", "Hello World"),
        ("Russian (Cyrillic)", "Привет, мир!"),
        ("Arabic", "مرحبا بالعالم"),
        ("Chinese (Han)", "你好世界"),
        ("Korean (Hangul)", "안녕하세요"),
        ("Japanese (Hiragana)", "こんにちは世界"),
        ("Hindi (Devanagari)", "नमस्ते दुनिया"),
        ("Thai", "สวัสดีชาวโลก"),
        ("Hebrew", "שלום עולם"),
    ]

    for script_name, text in test_texts:
        print(f"=== {script_name} ===")
        print(f"Text: {text}")

        # Detect script
        detected_script = manager.detect_script_in_text(text)
        if detected_script:
            print(f"Detected script: {detected_script.name}")

            # Get font recommendations
            recommendations = manager.get_recommended_fonts_for_script(detected_script)
            if recommendations:
                print("Recommended fonts:")
                for i, (font_name, font_path) in enumerate(recommendations[:3], 1):
                    print(f"  {i}. {font_name}")
            else:
                print("No specific font recommendations available")
        else:
            print("No specific script detected (likely Latin/Common)")

        print()


def demonstrate_error_handling():
    """Demonstrate improved error handling with font suggestions."""

    print("=== Error Handling Demo ===\n")

    # Simulate the error that would occur with Cyrillic text
    error_text = "ul. Zapadna obikolna, sgradа 8"
    font_name = "helvetica"

    print(f"Text causing error: {error_text}")
    print(f"Font that failed: {font_name}")
    print()

    # Get helpful error suggestion. A suggestion is only returned when an
    # installed font is verified to cover the offending characters; otherwise
    # fpdf2 falls back to the generic "Please consider using a Unicode font."
    suggestion = suggest_unicode_font_for_error(error_text, font_name)
    if suggestion:
        print("Helpful error message:")
        print(suggestion)
    else:
        print(
            "No installed font was verified to cover these characters; fpdf2 "
            "falls back to: 'Please consider using a Unicode font.'"
        )
    print()


def create_multilingual_pdf():
    """Create a PDF with multiple scripts using automatic font detection."""

    print("=== Creating Multilingual PDF ===\n")

    pdf = FPDF()
    pdf.add_page()

    # Initialize font manager
    manager = UnicodeFontManager()

    # Test texts in different scripts
    test_texts = [
        ("English", "Hello World - This is English text"),
        ("Russian (Cyrillic)", "Привет, мир! - Это русский текст"),
        ("Arabic", "مرحبا بالعالم - هذا نص عربي"),
        ("Chinese (Han)", "你好世界 - 这是中文文本"),
        ("Korean (Hangul)", "안녕하세요 - 이것은 한국어 텍스트입니다"),
        ("Japanese (Hiragana)", "こんにちは世界 - これは日本語のテキストです"),
        ("Hindi (Devanagari)", "नमस्ते दुनिया - यह हिंदी पाठ है"),
        ("Thai", "สวัสดีชาวโลก - นี่คือข้อความภาษาไทย"),
        ("Hebrew", "שלום עולם - זה טקסט בעברית"),
    ]

    y_position = 20

    for script_name, text in test_texts:
        # Get a font recommendation for this text. It is only returned when an
        # installed font is verified to actually cover the characters.
        recommendation = manager.get_font_recommendation_for_text(text)
        script = manager.detect_script_in_text(text)

        pdf.set_y(y_position)
        if recommendation:
            font_name, font_path = recommendation
            pdf.add_font(font_name, "", font_path)
            pdf.set_font(font_name, size=12)
            pdf.cell(0, 8, f"{script_name}: {text}", new_x="LMARGIN", new_y="NEXT")
            print(f"✓ {script_name}: Using {font_name}")
        elif script is None:
            # Latin text: the built-in font can render it.
            pdf.set_font("helvetica", size=12)
            pdf.cell(0, 8, f"{script_name}: {text}", new_x="LMARGIN", new_y="NEXT")
            print(f"• {script_name}: Using default font")
        else:
            # A non-Latin script with no installed font verified to cover it.
            # Render an ASCII note instead of the unsupported text, which the
            # built-in font could not encode.
            pdf.set_font("helvetica", size=12)
            pdf.cell(
                0,
                8,
                f"{script_name}: [no Unicode font covering this script found on this system]",
                new_x="LMARGIN",
                new_y="NEXT",
            )
            print(f"✗ {script_name}: no verified Unicode font available")
        y_position += 10

    # Save the PDF
    filename = "multilingual_unicode_demo.pdf"
    pdf.output(filename)
    print(f"\nPDF saved as: {filename}")


def demonstrate_convenience_function():
    """Demonstrate the convenience function for quick font recommendations."""

    print("=== Convenience Function Demo ===\n")

    # Test the convenience function
    test_texts = [
        "Привет, мир!",
        "مرحبا بالعالم",
        "你好世界",
        "Hello World",
    ]

    for text in test_texts:
        recommendation = get_unicode_font_recommendation(text)
        if recommendation:
            font_name, font_path = recommendation
            print(f"Text: {text}")
            print(f"Recommended font: {font_name}")
            print(f"Font path: {font_path}")
        else:
            print(f"Text: {text}")
            print("No specific recommendation (likely Latin text)")
        print()


if __name__ == "__main__":
    print("fpdf2 Unicode Font Detection Tutorial")
    print("=" * 50)
    print()

    try:
        # Run demonstrations
        demonstrate_unicode_font_detection()
        demonstrate_error_handling()
        demonstrate_convenience_function()
        create_multilingual_pdf()

        print("Tutorial completed successfully!")

    except Exception as e:
        print(f"Error during tutorial: {e}")
        print("This might be due to missing fonts on your system.")
        print("The functionality will work when appropriate fonts are available.")
Adding and Using Fonts
Before using a Unicode font, you need to load it from a font file. Usually you'll have call add_font() for each style of the same font family you want to use. The styles that fpdf2 understands are:
- Regular: ""
- Bold: "b"
- Italic/Oblique: "i"
- Bold-Italic: "bi"
Note that we use the same family name for each of them, but load them from different files. Only when a font has variants (eg. "narrow"), or there are more styles than the four standard ones (eg. "black" or "extra light"), you'll have to add those with a different family name. If the font files are not located in the current directory, you'll have to provide a file name with a relative or absolute path. If the font is not found elsewhere, then fpdf2 will look for it in a subdirectory named "font".
from fpdf import FPDF

pdf = FPDF()
pdf.add_page()
# Different styles of the same font family.
pdf.add_font("dejavu-sans", style="", fname="DejaVuSans.ttf")
pdf.add_font("dejavu-sans", style="b", fname="DejaVuSans-Bold.ttf")
pdf.add_font("dejavu-sans", style="i", fname="DejaVuSans-Oblique.ttf")
pdf.add_font("dejavu-sans", style="bi", fname="DejaVuSans-BoldOblique.ttf")
# Different type of the same font design.
pdf.add_font("dejavu-sans-narrow", style="", fname="DejaVuSansCondensed.ttf")
pdf.add_font("dejavu-sans-narrow", style="i", fname="DejaVuSansCondensed-Oblique.ttf")
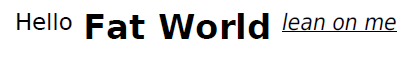
To actually use the loaded font, or to use one of the standard built-in fonts, you'll have to set the current font before calling any text generating method. .set_font() uses the same combinations of family name and style as arguments, plus the font size in typographic points. In addition to the previously mentioned styles, the letter u may be included for creating underlined text, and s for creating strikethrough text. If the family or size are omitted, the already set values will be retained. If the style is omitted, it defaults to regular.
# Set and use first family in regular style.
pdf.set_font(family="dejavu-sans", style="", size=12)
pdf.cell(text="Hello")
# Set and use the same family in bold style.
pdf.set_font(style="b", size=18)  # still uses the same dejavu-sans font family.
pdf.cell(text="Fat World")
# Set and use a variant in italic and underlined.
pdf.set_font(family="dejavu-sans-narrow", style="iu", size=12)
pdf.cell(text="lean on me")
Note on non-latin languages
Many non-latin writing systems have complex ways to combine characters, ligatures, and possibly multiple diacritic symbols together, change the shape of characters depending on its location in a word, or use a different writing direction. A small number of examples are:
- Hebrew - right-to-left, placement of diacritics
- Arabic - right-to-left, contextual shapes
- Thai - stacked diacritics
- Devanagari (and other indic scripts) - multi-character ligatures, reordering
To make sure those scripts to be rendered correctly, text shaping must be enabled with .set_text_shaping(True).
Right-to-Left scripts
When text shaping is enabled, fpdf2 will apply the Unicode Bidirectional Algorithm to render correctly any text, including bidirectional (mix of right-to-left and left-to-right scripts).
Example
This example uses several free fonts to display some Unicode strings. Be sure to install the fonts in the font directory first.
#!/usr/bin/env python
# -*- coding: utf8 -*-

from fpdf import FPDF

pdf = FPDF()
pdf.add_page()
pdf.set_text_shaping(True)

# Add a DejaVu Unicode font (uses UTF-8)
# Supports more than 200 languages. For a coverage status see:
# http://dejavu.svn.sourceforge.net/viewvc/dejavu/trunk/dejavu-fonts/langcover.txt
pdf.add_font(fname='DejaVuSansCondensed.ttf')
pdf.set_font('DejaVuSansCondensed', size=14)

text = u"""
English: Hello World
Greek: Γειά σου κόσμος
Polish: Witaj świecie
Portuguese: Olá mundo
Russian: Здравствуй, Мир
Vietnamese: Xin chào thế giới
Arabic: مرحبا العالم
Hebrew: שלום עולם
"""

for txt in text.split('\n'):
    pdf.write(8, txt)
    pdf.ln(8)

# Add a Indic Unicode font (uses UTF-8)
# Supports: Bengali, Devanagari, Gujarati,
#           Gurmukhi (including the variants for Punjabi)
#           Kannada, Malayalam, Oriya, Tamil, Telugu, Tibetan
pdf.add_font(fname='gargi.ttf')
pdf.set_font('gargi', size=14)
pdf.write(8, u'Hindi: नमस्ते दुनिया')
pdf.ln(20)

# Add a AR PL New Sung Unicode font (uses UTF-8)
# The Open Source Chinese Font (also supports other east Asian languages)
pdf.add_font(fname='fireflysung.ttf')
pdf.set_font('fireflysung', size=14)
pdf.write(8, u'Chinese: 你好世界\n')
pdf.write(8, u'Japanese: こんにちは世界\n')
pdf.ln(10)

# Add a Alee Unicode font (uses UTF-8)
# General purpose Hangul truetype fonts that contain Korean syllable
# and Latin9 (iso8859-15) characters.
pdf.add_font(fname='Eunjin.ttf')
pdf.set_font('Eunjin', size=14)
pdf.write(8, u'Korean: 안녕하세요')
pdf.ln(20)

# Add a Fonts-TLWG (formerly ThaiFonts-Scalable) (uses UTF-8)
pdf.add_font(fname='Waree.ttf')
pdf.set_font('Waree', size=14)
pdf.write(8, u'Thai: สวัสดีชาวโลก')
pdf.ln(20)

# Select a standard font (uses windows-1252)
pdf.set_font('helvetica', size=14)
pdf.ln(10)
pdf.write(5, 'This is standard built-in font')

pdf.output("unicode.pdf")
View the result here: unicode.pdf
Free Font Pack
For your convenience, the author of the original PyFPDF has collected 96 TTF files in an optional "Free Unicode TrueType Font Pack for FPDF", with useful fonts commonly distributed with GNU/Linux operating systems. Note that this collection is from 2015, so it will not contain any newer fonts or possible updates.
Fallback fonts
New in 2.7.0
The method set_fallback_fonts() allows you to specify a list of fonts to be used if any character is not available on the font currently set. When a character doesn’t exist on the current font, fpdf2 will look if it’s available on the fallback fonts, on the same order the list was provided.
Common scenarios are use of special characters like emojis within your text, greek characters in formulas or citations mixing different languages.
Example:
import fpdf

pdf = fpdf.FPDF()
pdf.add_page()
pdf.add_font(fname="Roboto.ttf")
# twitter emoji font: https://github.com/13rac1/twemoji-color-font/releases
pdf.add_font(fname="TwitterEmoji.ttf")
pdf.set_font("Roboto", size=15)
pdf.set_fallback_fonts(["TwitterEmoji"])
pdf.write(text="text with an emoji 🌭")
pdf.output("text_with_emoji.pdf")
When a glyph cannot be rendered uing the current font, fpdf2 will look for a fallback font matching the current character emphasis (bold/italics). By default, if it does not find such matching font, the character will not be rendered using any fallback font. This behaviour can be relaxed by passing exact_match=False to set_fallback_fonts().
Moreover, for more control over font fallback election logic, the get_fallback_font() can be overridden. An example of this can be found in test/fonts/test_font_fallback.py.
Unicode range limits
New in 2.8.5
The unicode_range parameter in add_font() allows you to restrict which Unicode characters a font will handle, similar to CSS @font-face unicode-range rules. This gives you fine-grained control over font priority on a per-character basis.
This is particularly useful when you want fallback fonts to take priority for specific character ranges, even when the main font technically supports those characters. A common scenario is preferring colorful emoji fonts over monochrome glyphs that exist in regular fonts.
Example:
from fpdf import FPDF

pdf = FPDF()
pdf.add_page()

# Main font for text
pdf.add_font(family="DejaVu", fname="DejaVuSans.ttf", unicode_range="U+0020-007E")

# Emoji font restricted to emoticons range only
pdf.add_font(
    family="NotoEmoji",
    fname="colrv1-NotoColorEmoji.ttf",
    unicode_range="U+1F600-1F64F",  # Emoticons
)

pdf.set_font("DejaVu", size=24)
pdf.set_fallback_fonts(["NotoEmoji"])

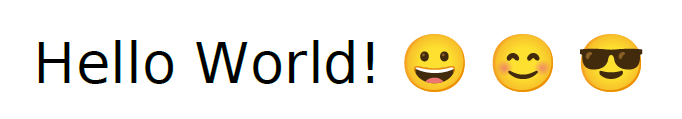
# Emojis in the specified range render from NotoEmoji (colorful)
pdf.write(text="Hello World! 😀 😊 😎")
pdf.output("emoji_with_unicode_range.pdf")
Supported Formats for unicode_range param
# CSS-style string with comma-separated ranges
pdf.add_font(fname="font.ttf", unicode_range="U+1F600-1F64F, U+2600-26FF, U+2615")

# List of strings
pdf.add_font(fname="font.ttf", unicode_range=["U+1F600-1F64F", "U+2600", "U+26FF"])

# List of tuples (start, end)
pdf.add_font(fname="font.ttf", unicode_range=[(0x1F600, 0x1F64F), (0x2600, 0x26FF)])

# List of integers (individual codepoints)
pdf.add_font(fname="font.ttf", unicode_range=[0x1F600, 0x2600, 128512])
When you specify a unicode_range, the font's internal character map (cmap) is trimmed to only include codepoints within the specified ranges. This ensures that:
- The font will only be used for characters in its allowed ranges
- Fallback fonts can take priority for characters outside those ranges
- You avoid unwanted "fallback pollution" from fonts with poor-quality glyphs
For more information on fallback fonts, see the Fallback fonts section.
Variable Fonts
New in 2.8.5
A variable font allows users to use a single font file containing many variations of a typeface, such as weight, width, optical size, and slant. Each such variable which modifies the typeface is called an axis. These variables have specific tags which are used to specify their values, such as "wdth" for modifying width, and "wght" for modifying weight. For a full list of tags, please check the documentation of your variable font.
The variations parameter in add_font allows you to specify the value of one or more axes, thus creating a static font from the variable font.
The following examples assume that the provided font is a variable font.
# Specify width and weight in regular style.
pdf.add_font(
    "Roboto Variable", "", "Roboto-Variable.ttf", variations={"wdth": 75, "wght": 300}
)

# Specify weight for bold style.
pdf.add_font("Roboto Variable", "B", "Roboto-Variable.ttf", variations={"wght": 600})
The above examples provide the axes dictionary to specify the styles. If an axis is not mentioned, the default width will be used, and the axis will be dropped as shown below.
# Creating an italic version of the variable font.
# If an axis is set to None, or if the axis is unspecified,
# it will not be variable in the created font.
pdf.add_font(
    "Roboto Variable",
    "B",
    "Roboto-Variable.ttf",
    variations={"wght": 800, "wdth": None},
)
It is also possible to specify more than 1 style in the variations dictionary. If a separate axes dictionary is specified for each style, then the style parameter is ignored as shown below.
pdf.add_font(
    "Roboto Variable",
    style="", # ignored
    fname="Roboto-Variable.ttf",
    variations={"": {"wght": 300}, "B": {"wght": 700}},
)
TypeError will be raised if variations is not a dictionary, and an AttributeError will be raised if variations is used but the font is not a variable font. Color Font Palette Selection
New in 2.8.5
Some color fonts (COLRv0, COLRv1, CBDT, SBIX, SVG) contain multiple predefined color palettes. The palette parameter in add_font() allows you to select which palette to use when rendering the font.
This is useful when you want to use different color schemes from the same font file without having to embed the font multiple times.
Example:
from fpdf import FPDF

pdf = FPDF()
pdf.add_page()

# Add the same color font with different palettes using different family names
pdf.add_font(
    family="Nabla-Default",
    fname="Nabla-Regular-COLRv1.ttf",
    palette=0  # Use palette 0 (default)
)

pdf.add_font(
    family="Nabla-Blue",
    fname="Nabla-Regular-COLRv1.ttf",
    palette=1  # Use palette 1
)

pdf.add_font(
    family="Nabla-Grey",
    fname="Nabla-Regular-COLRv1.ttf",
    palette=2  # Use palette 2
)

# Use the fonts with different palettes
pdf.set_font("Nabla-Default", size=24)
pdf.cell(text="Text with Palette 0", new_x="lmargin", new_y="next")

pdf.set_font("Nabla-Blue", size=24)
pdf.cell(text="Text with Palette 1", new_x="lmargin", new_y="next")

pdf.set_font("Nabla-Grey", size=24)
pdf.cell(text="Text with Palette 2", new_x="lmargin", new_y="next")

pdf.output("color_font_palettes.pdf")
If you specify a palette index that is out of range, fpdf2 will log a warning and fall back to palette 0. You can check the number of available palettes in your color font's documentation or by inspecting the font file.